








The short version
Throughput that holds, and costs you can explain.
The whole engineering process
Systems design, UX, build, testing and documentation from one team, so nothing gets lost between the people who designed it and the people who built it.
Data pipelines and orchestration
The core of everything we build. Ingestion, transformation and the jobs that run them, sized for millions of rows and increased usage spikes.
AI where it pays
We add AI where your data has no fixed shape: PDFs, emails, scanned documents and web content, parsed into clean, structured records your systems can use.
Systems design and UX
Architecture, data model and interfaces agreed up front, with a prototype you can click before the first line of production code.
Ingestion at volume
Data from every source — APIs, files, databases and events — landed in one clean shape, at whatever volume your product reaches.
Document extraction
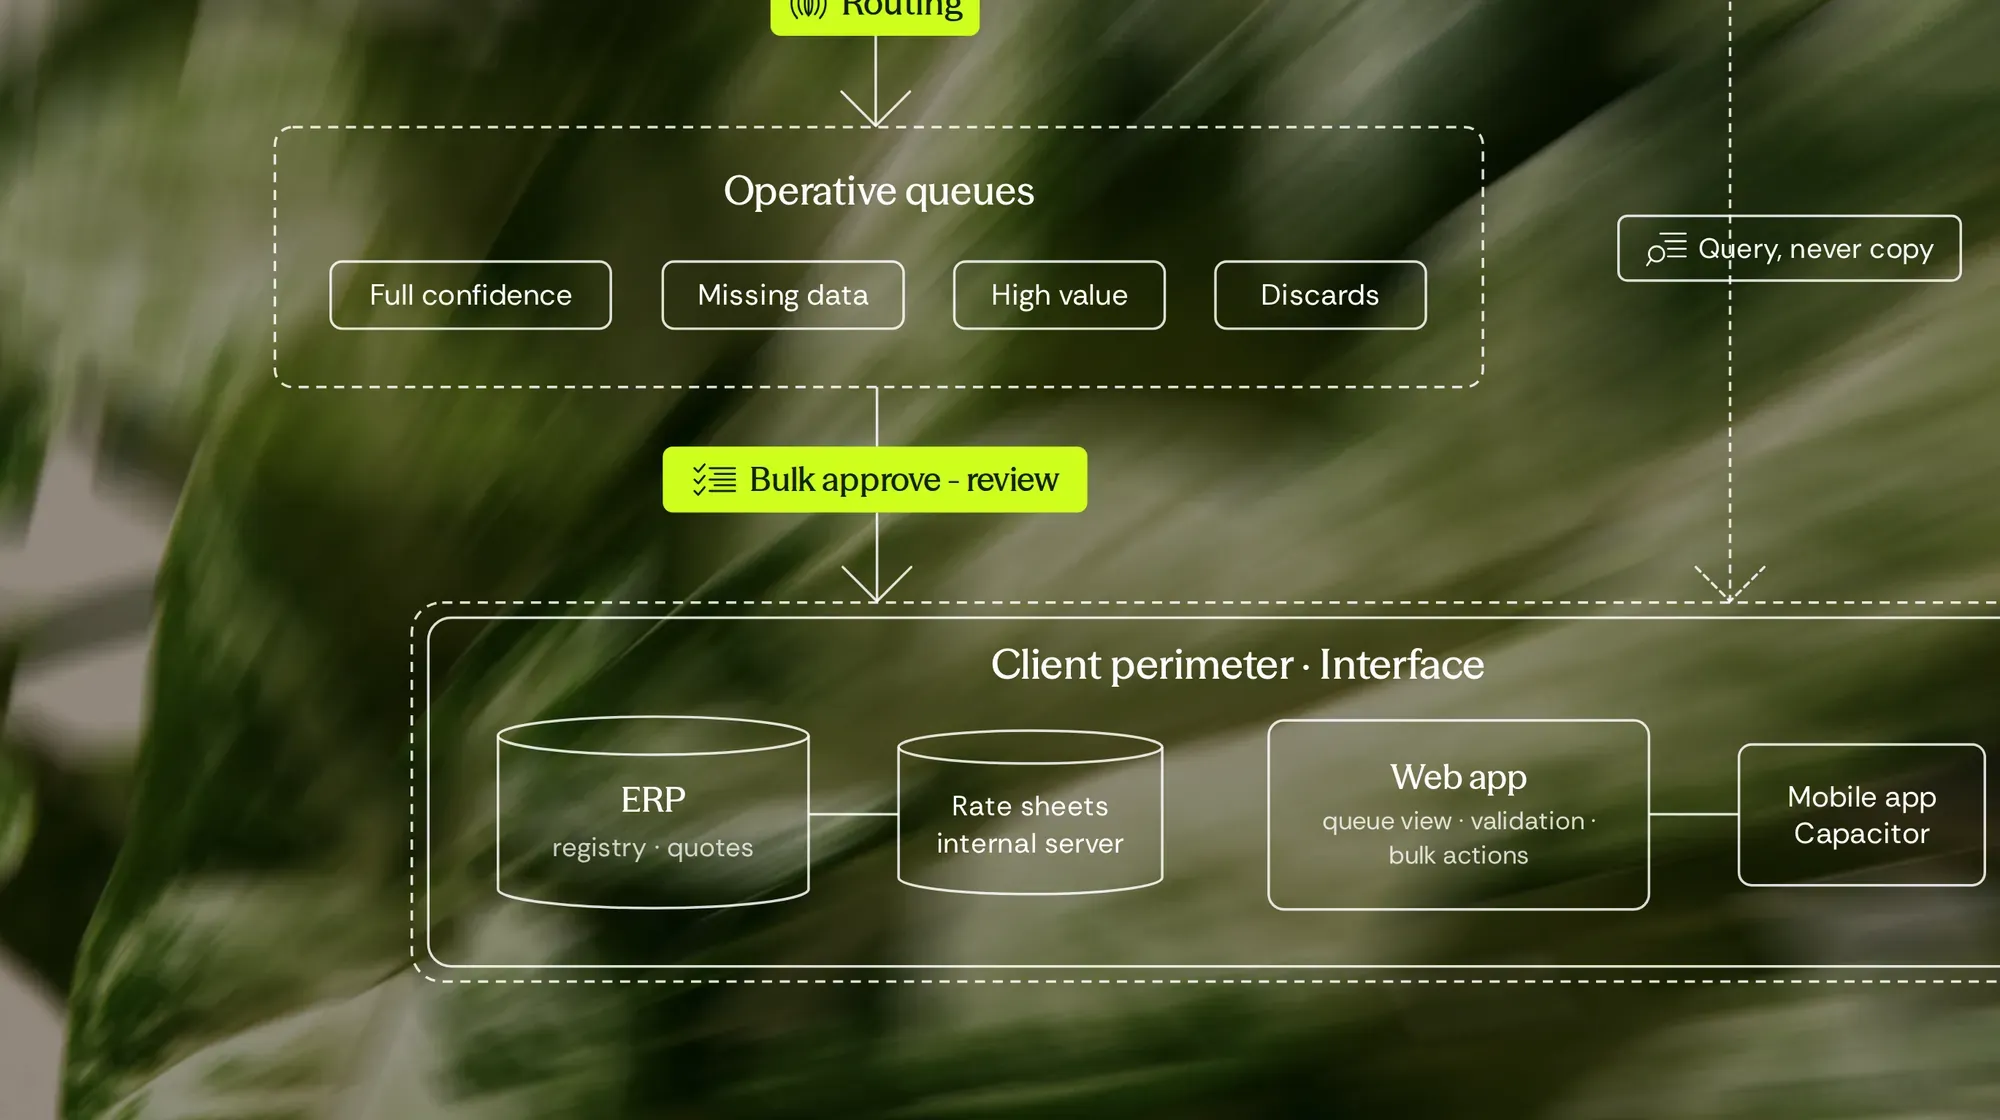
Invoices, delivery notes and contracts turned into fields, with a confidence score and a person reviewing what falls below it.
Documentation that ships
Architecture notes, runbooks and API references delivered with the code, so the next engineer starts from a document, not from guesswork.
Microservice orchestration
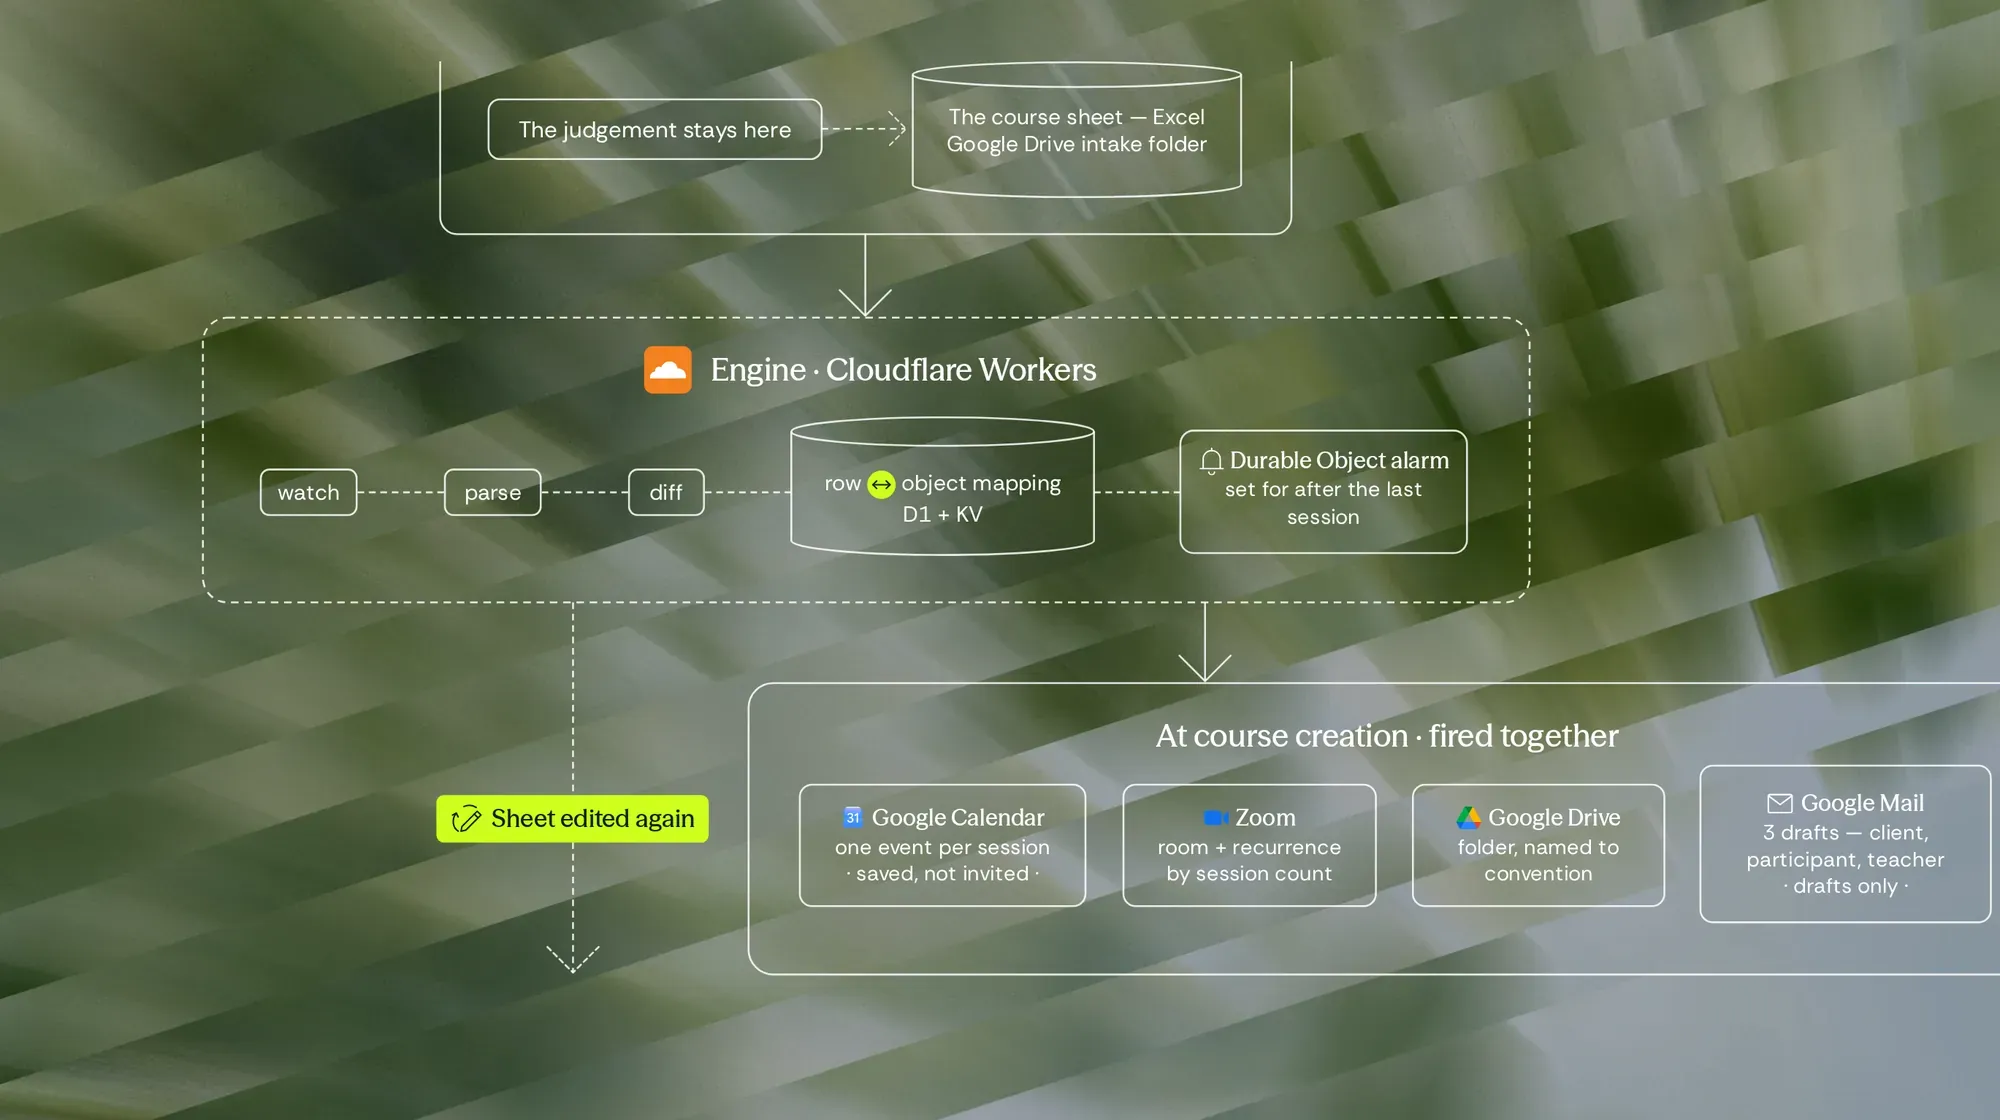
What runs, in what order, and what happens when step four fails at 3 a.m. — designed, with a run history that explains itself.
Transactional email and alerts
Notices to your users, plus alerts to your team when part of the system fails and when it recovers — built into every project.
Throughput that holds
Built for your busiest day, not your average one — so growth never turns into an outage.
Costs you can explain
Sized for the actual load and continuously monitored and optimized after launch — so the cloud bill remains clear, efficient and anchored to your product’s true compute requirements.
Spark is not a data-science engagement or a staffing contract. We don’t build BI dashboards or sell prompts as a deliverable. We take on the product and the engineering behind it — including training models where relevant.
What does a Spark project include?
The whole engineering process: systems design, UX and prototyping, build, testing and documentation. The quote splits the days into design, build and architecture work, so you can see where the effort goes before anything starts.
Which model providers do you use?
Whichever you choose to send your data to. That is primarily a procurement and GDPR data privacy concern, and it’s settled during scoping rather than assumed.
What happens when the model gets it wrong?
Every extraction carries a confidence score, and every low-confidence result goes to a person. We always design AI pipelines with humans in the loop.
Where does my cloud infrastructure run?
By default, we use the Cloudflare Workers platform, an extremely efficient serverless environment both cost- and performance-wise. If you have cloud preferences, such as AWS, Azure or other providers, let us know. Depending on complexity, managing different cloud providers at once may incur slightly higher quotes due to the additional configuration and maintenance required. Cloudflare stays our default for everything we build and maintain.
Something that has to be built, and has to scale?
Tell us what you’re building and the volume it has to handle. Datsugi replies within 2 business hours, guaranteed (CET).
Arrigo Lupori
Founder & Managing Director